Intelligence Is Getting Unbundled
7 October 2026
On September 29, OpenAI launched Ultrafast at DevDay, their developer conference.
What is Ultrafast?
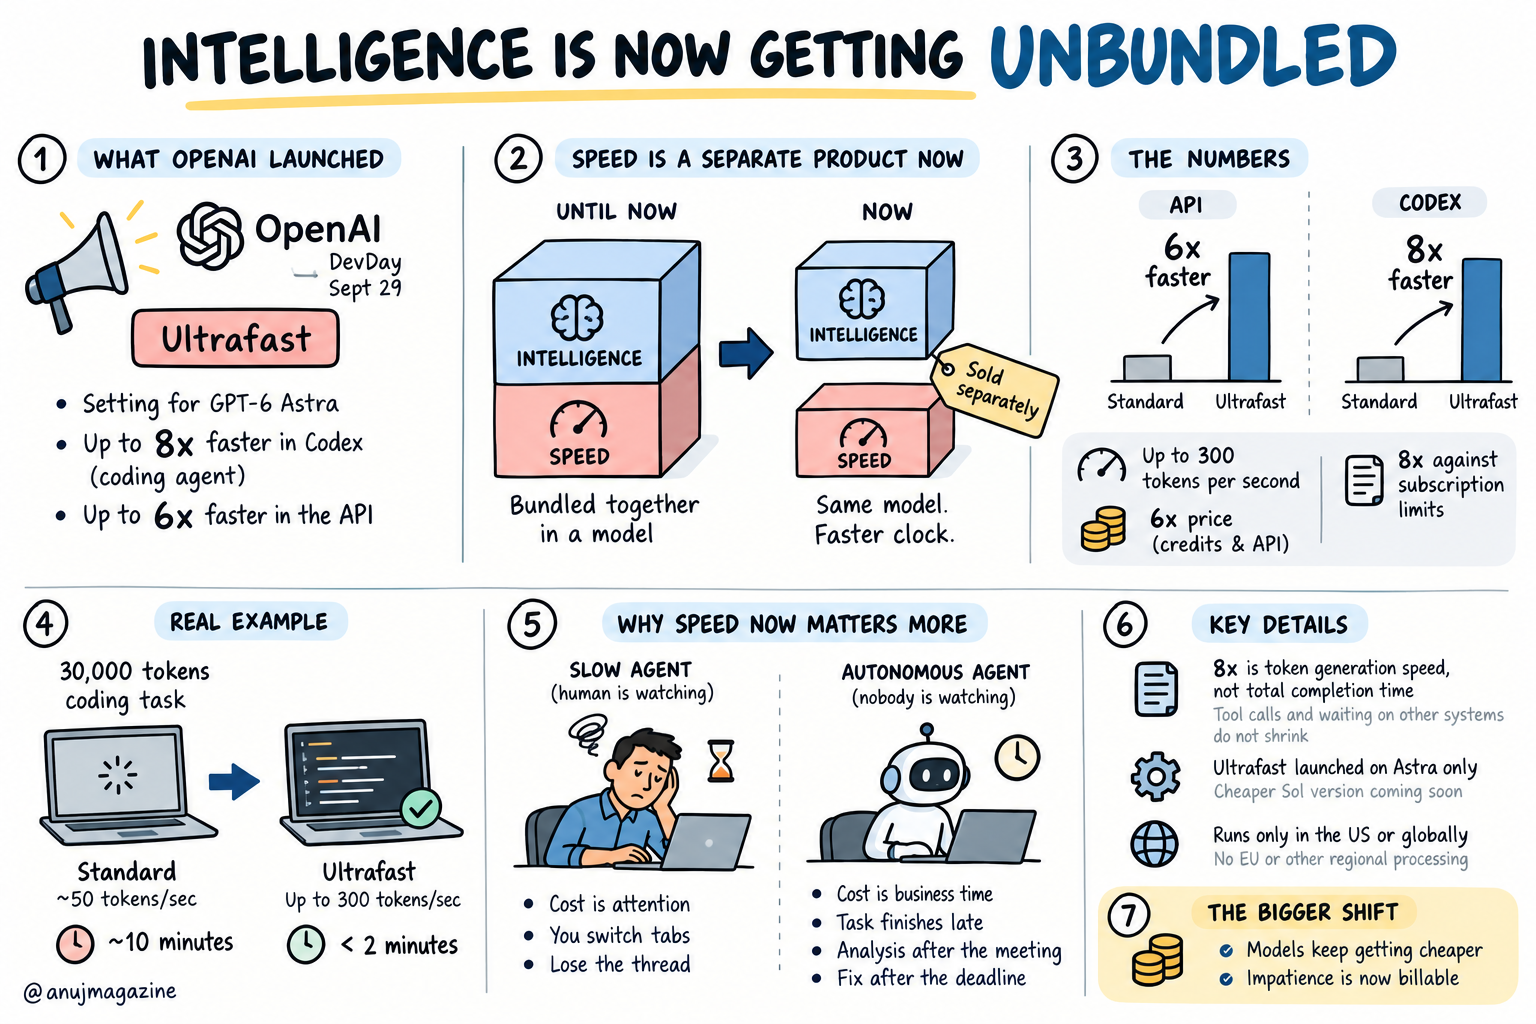
It is a setting that makes its top model, GPT-6 Astra, write answers up to 8x faster in Codex, its coding agent, and up to 6x in the API.
The broader change is that the speed of AI is now a component with its own price, being sold separately from the model.
Until now, faster answers mostly came with a new model, so speed was bundled with intelligence. OpenAI did already sell a Fast mode, but it was a small surcharge: about 1.5x faster for twice the usage in Codex. Ultrafast is the first time the two are properly unbundled. Same model, a faster clock of up to 300 tokens per second, at 6x the standard price on credits and the API, and 8x against subscription limits, per OpenAI’s docs.
Take one long coding task that writes 30,000 tokens. At roughly 50 tokens per second, that is 10 minutes of waiting. On Ultrafast it is under 2 minutes.
When a person works with a slow agent, the cost is attention. They switch tabs, lose the thread, come back later. When the agent is autonomous, nobody is watching, so the cost lands on the business as plain time. An agent working through a long chain of steps finishes late, the analysis arrives after the meeting, the fix after the deadline. Seen that way, 6x is a quote for how much an hour of delay is worth to the buyer.
Some finer points in the official docs:
- OpenAI says the 8x is token generation speed, not total completion time, so tool calls and waiting on other systems do not shrink.
- Ultrafast launched on Astra only, with the cheaper Sol version coming soon.
- It runs only in the US or globally, with no EU or other regional processing.
Intelligence used to arrive bundled with speed. Speed is now one of the first pieces to be sold on its own. Models keep getting cheaper. Impatience is what is now billable.